

 All Categories
Built for How Business Buys.
All Categories
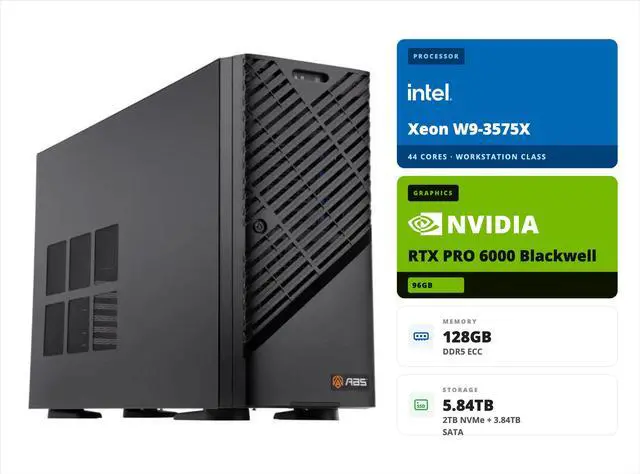


Stop renting GPUs. The Zaurion Aqua puts data-center silicon in a quiet tower: 96 GB of GDDR7 on a single professional Blackwell card, a flagship Xeon W backbone, and Ubuntu ready for CUDA on first boot. Your models, your data, your hardware — zero cloud bills.

The rear panel reads like a datacenter spec sheet. Hover each marker (or read the legend) to see what this workstation-class I/O actually buys you.
 1
Dual 10 GbE + management LANWire-speed dataset transfers to your NAS or cluster, plus out-of-band IT control.
2
Directed exhaust airflowEngineered cooling keeps CPU and GPU at full boost through multi-day runs.
3
Quad DisplayPort on the RTX PRO 6000Drive multi-monitor and 8K-class displays with DisplayPort 2.1.
4
Full-height PCIe expansionServer-class Gigabyte MW83-RP0 board with room for future accelerators and NICs.
5
2000 W 80 PLUS Gold PSUEfficient, stable headroom for sustained full-load GPU training.
A 100 GB corpus lands in minutes, not hours — and IT can power-cycle and monitor the box remotely, even when the OS is down.
Internal airflow diversion sustains full boost clocks around the clock.
DisplayPort 2.1 bandwidth for color-accurate multi-monitor and 8K-class work.
The server-grade Gigabyte MW83-RP0 platform leaves lanes for tomorrow's cards.
One PSU, zero drama — headroom for the GPU, CPU, and everything you add.
Business and prosumer workloads this exact configuration was built for — no hypotheticals.

Serve large open-weight models to the whole team with an OpenAI-compatible API. Zero per-token bills; nothing leaves your firewall.

Adapt models to your domain — support transcripts, contracts, catalogs. LoRA fits in 96 GB; optional aiDAPTIV unlocks full fine-tuning of ~34B models.3

Index wikis, tickets, and manuals; employees ask in plain language, answers come back grounded with sources — all on-prem.

Agents that read tickets, draft replies, and chain multi-step tasks — optionally shipped with OpenClaw or NemoClaw pre-installed.

4th-gen RT Cores drive photoreal ray tracing for product design, AECO, and digital twins; 96 GB holds scenes smaller cards can't open.

9th-gen NVENC and 6th-gen NVDEC accelerate encode and ingest, including 4:2:2 H.264/HEVC, for editing suites and live production.
Scene photos are AI-generated illustrations of typical deployments, not photographs of this exact product.
Illustrative comparison of usable GPU memory for model loading.
Storage ships ready for real work — a 2 TB M.2 NVMe system drive plus a 3.84 TB data SSD — and the optional Pascari aiDAPTIV SSD tier rewrites the fine-tuning math:
| Target Model Size | VRAM Needed (Without aiDAPTIV) | VRAM Needed (With aiDAPTIV) |
|---|---|---|
| ~13B | 120–200 GB | 32 GB |
| ~34B | 250–350 GB | 96 GB — this workstation's GPU |
| ~70B | 500–700 GB | 192 GB |
Pascari aiDAPTIV SSD is an optional add-on and is not included by default. VRAM figures are vendor-published estimates for full fine-tuning.3
Illustrative deployment profiles — and the Build-to-Order options that fit each one:

Inference by day, LoRA runs by night. Pair with the Local LLM Package (Qwen 3.5 27B or higher, pre-configured) and skip setup week entirely.
MIG gives each researcher an isolated GPU slice; TAA compliance and USA assembly clear public-sector purchasing. Add the Pascari aiDAPTIV SSD for full fine-tuning headroom.3
Order it with OpenClaw or NemoClaw pre-installed and ship ticket-triage and code-review agents in week one, isolated per MIG partition.
Same Xeon W9-3575X platform with 2× RTX PRO 6000 Blackwell MaxQ for maximum combined GPU memory — compare options on this listing.
Xeon W5-2455X with the same 96 GB Blackwell GPU — the budget door into large-model territory.
Every unit is assembled and stress-tested in the USA to your configuration — request a quote or customize from this page.
Yes. 96 GB of GDDR7 on a single card loads large open-weight models (Qwen, Llama, and similar) for inference and LoRA fine-tuning; the optional aiDAPTIV tier extends full fine-tuning to ~34B-class models.3
Ubuntu comes pre-installed — the native home of CUDA, PyTorch, vLLM, and the open-source AI stack.
Yes. Universal MIG partitions the GPU into isolated instances, and 2 × 10 Gb/s LAN ports serve model APIs to your whole team at wire speed.
It is TAA compliant and assembled in the USA, with compliance documents available for purchase review.
1-year parts and labor limited warranty backed by ABS manufacturer support. As a Build to Order system, it is custom built and stress-tested after purchase.


