

 All Categories
Built for How Business Buys.
All Categories
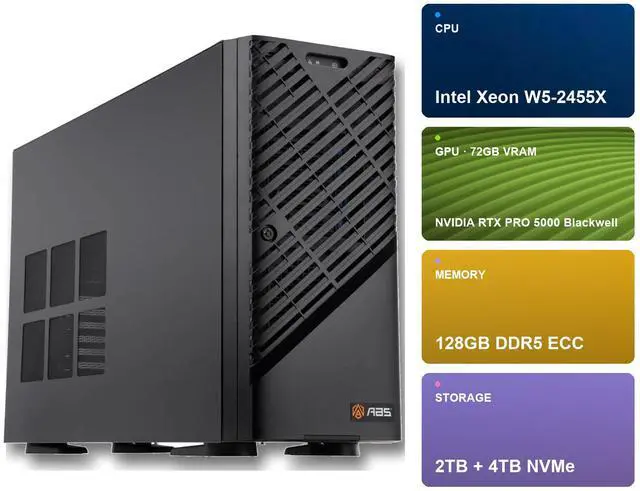
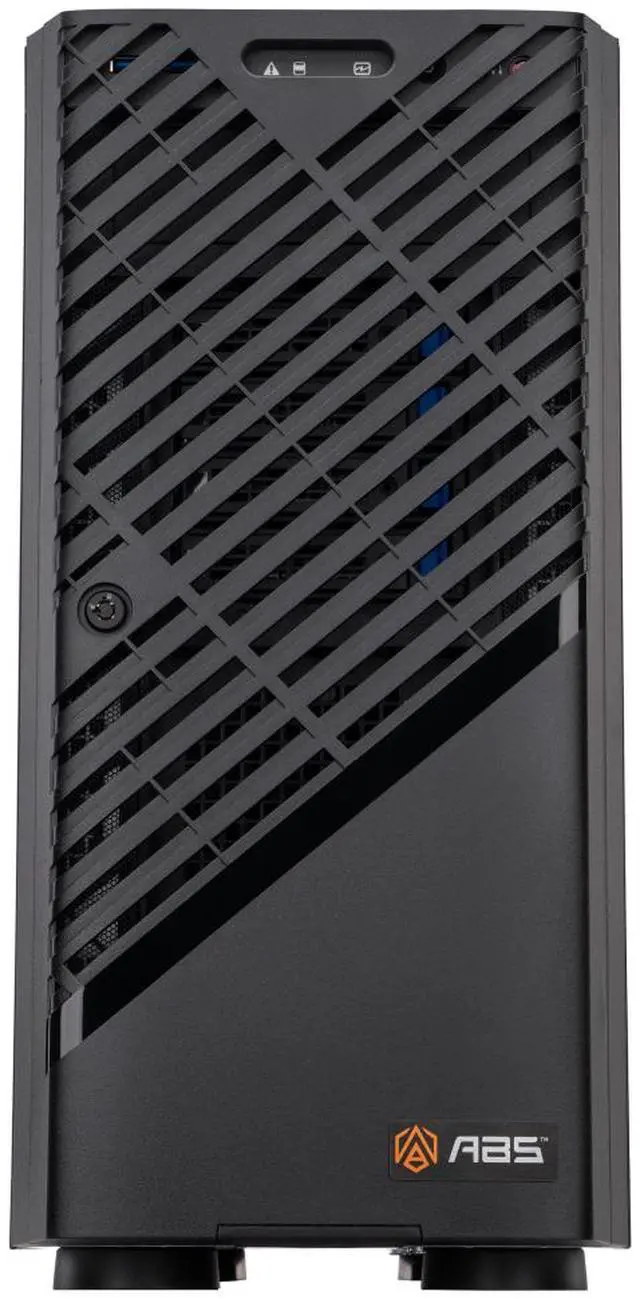
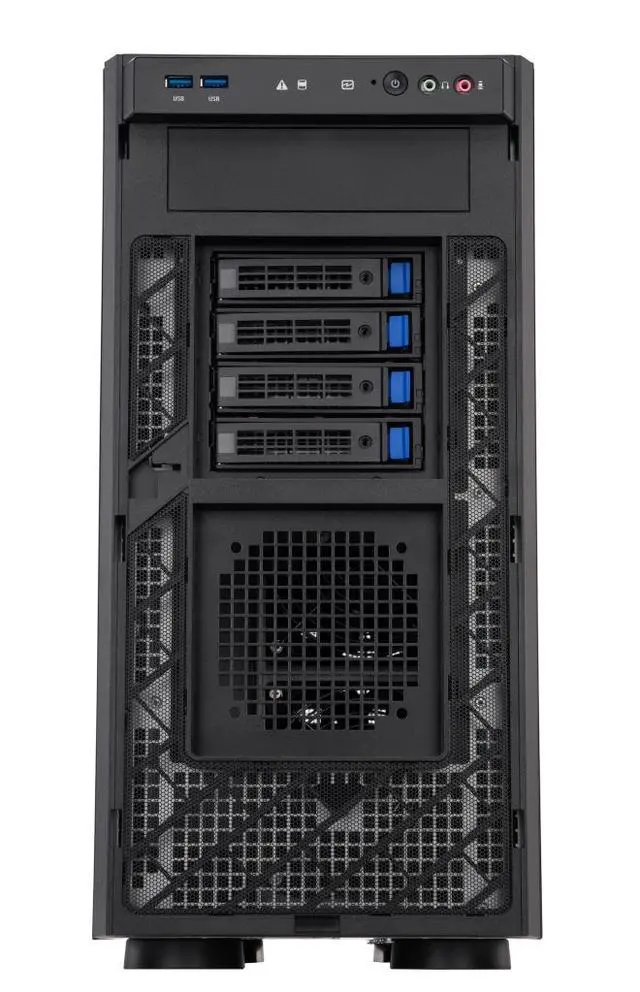
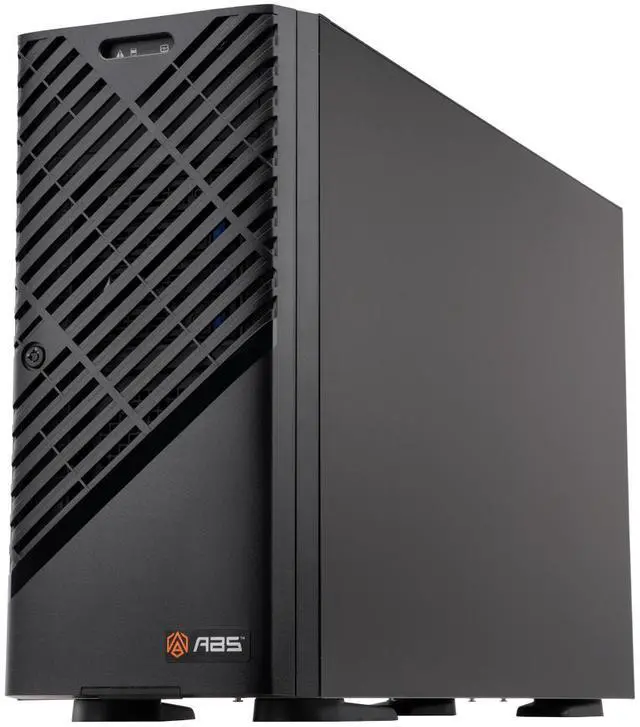
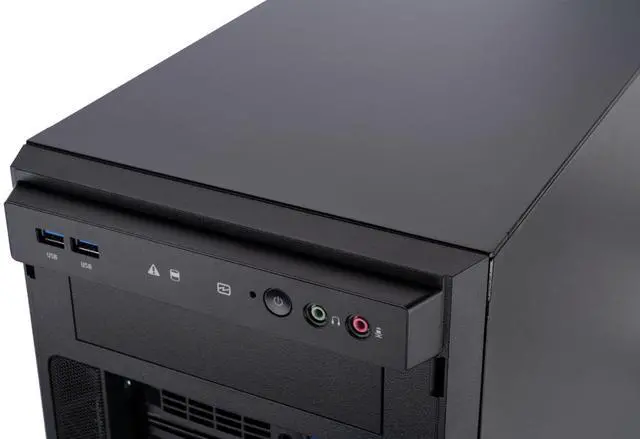
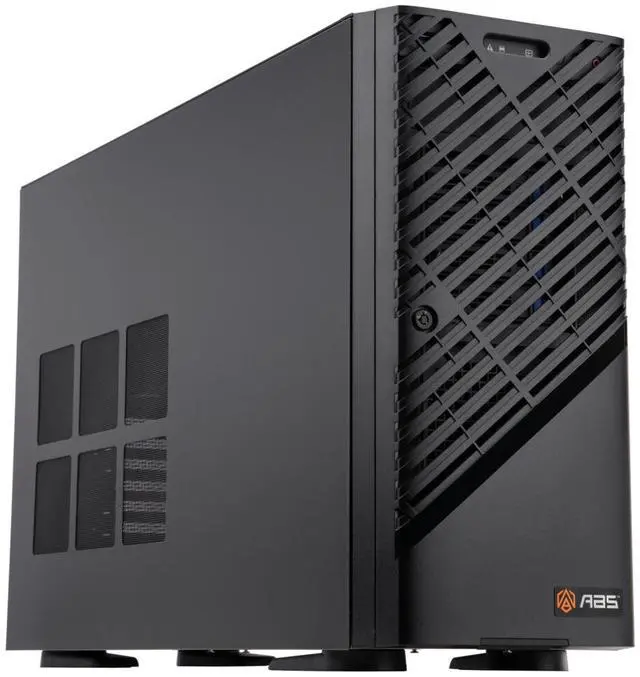


A 12-core, 24-thread Intel Xeon keeps the accessible entry point into this GPU memory tier affordable, without shrinking the GPU that matters. 72 GB of GDDR7 is enough to develop, fine-tune, and run local AI models in the tens of billions of parameters — right on the desk beside you. Kick off a fine-tuning run before a meeting, and it's done by the time you're back — the kind of local iteration speed that turns "let's check tomorrow" into "let's check right now."

An accessible CPU tier next to a memory-rich professional GPU, sized for real local AI work rather than benchmarks:
GPU memory is the real ceiling on local model size. Here's the honest, illustrative math for what fits — not a benchmark, just the arithmetic:
Illustrative, approximate rule-of-thumb math (bytes-per-parameter × model size), not a vendor benchmark. Actual usable capacity depends on context length, batch size, and framework overhead.
The listing's own AI Features, translated into what this specific configuration can actually do:

With 72GB of GPU memory, iterate on 30B-class models at full precision, or up to roughly 70B quantized, entirely on this desk. Kick off a run, step away, and it's done — fast local development loops without a cloud API bill.

12 cores / 24 threads keep data loading and preprocessing moving while the GPU handles the heavy lifting; 128GB of system memory holds large in-memory datasets.

PCIe Gen 5 bandwidth between CPU and GPU, plus Blackwell's mixed-precision Tensor Cores, keep simulation workloads fed with data instead of waiting on it.

72GB of VRAM holds large scene and texture data without the memory-driven quality trade-offs that stall lower-capacity cards, with RT Cores accelerating the preview.

Blackwell-generation video engines accelerate encode and decode for multi-stream editing, while 24 CPU threads handle timeline scrubbing and effects in parallel.

The same 72GB GPU that runs local AI models also drives real-time ray-traced previews inside the engine editor — AI tooling and graphics work on one machine.
Scene photos are AI-generated illustrations of typical deployments, not photographs of this exact product.
A 72GB professional GPU on your own desk changes the economics and the guarantees of running AI workloads, not just the raw performance:

Illustrative framing of the ownership trade-off, not a cost model for any specific cloud provider or workload.
| ZAW5-2455X-RP500072 | |
|---|---|
| CPU | Intel Xeon W5-2455X — 12-core / 24 threads, LGA46771 |
| GPU | NVIDIA RTX PRO 5000 Blackwell — 72 GB GDDR7 |
| Memory | 128 GB DDR5, ECC Registered |
| Storage | 2 TB M.2 NVMe (OS) + 4 TB M.2 NVMe (Data) |
| Networking | 2× 10 Gb/s LAN + 1× 10/100/1000 Mbps management LAN |
| Motherboard | Gigabyte MW83-RP0 (Gigabyte W773-W80 barebone) |
| Power | Single 2000 W ATX 80 PLUS Gold |
| Expansion | 8× RDIMM (8-channel DDR5), 5× PCIe 5.0 x16 + 2× PCIe 4.0 x16, 2× M.2 (both populated) |
| OS | Ubuntu |
| Optional | OpenClaw agent framework (pre-installed); Qwen 3.5 27B+ local LLM package |
Illustrative rule-of-thumb math, not a vendor benchmark: roughly 30B parameters at full FP16 precision, roughly 65B at INT8, or roughly 130B at INT4. Actual usable capacity depends on context length, batch size, and framework overhead.
It's the accessible entry point into this chassis lineup's 72GB GPU tier — 12 cores and 24 threads are enough to keep data loading, preprocessing, and orchestration ahead of the GPU, not behind it.
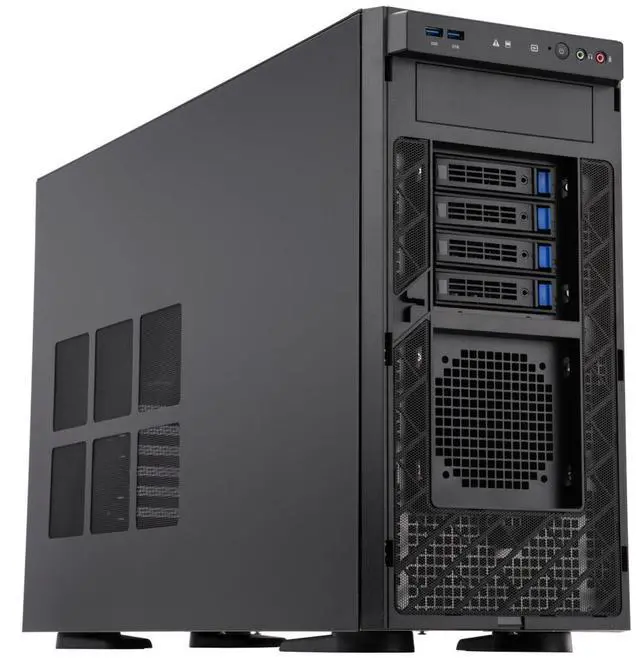
Both of the platform's 2 M.2 slots are populated (2TB OS + 4TB data). The case's 4 installed SATA hot-swap bays (plus 4 more optional) are open, since this configuration is all-NVMe.
The AI agent framework (OpenClaw) is pre-installed; a Qwen 3.5 27B or higher local LLM package is an optional add-on configured at order time.
It is TAA compliant and assembled in the USA, with compliance documents available for purchase review.
1-year parts and labor limited warranty backed by ABS manufacturer support. As a Build to Order system, it is custom built and stress-tested after purchase.